Fix “No voice found”
1
Check which microphone is active
The active input device shows in the top-right of every settings pane. If Superwhisper is listening to the wrong device, such as a disconnected headset or a muted external microphone, switch it there or set Use system default.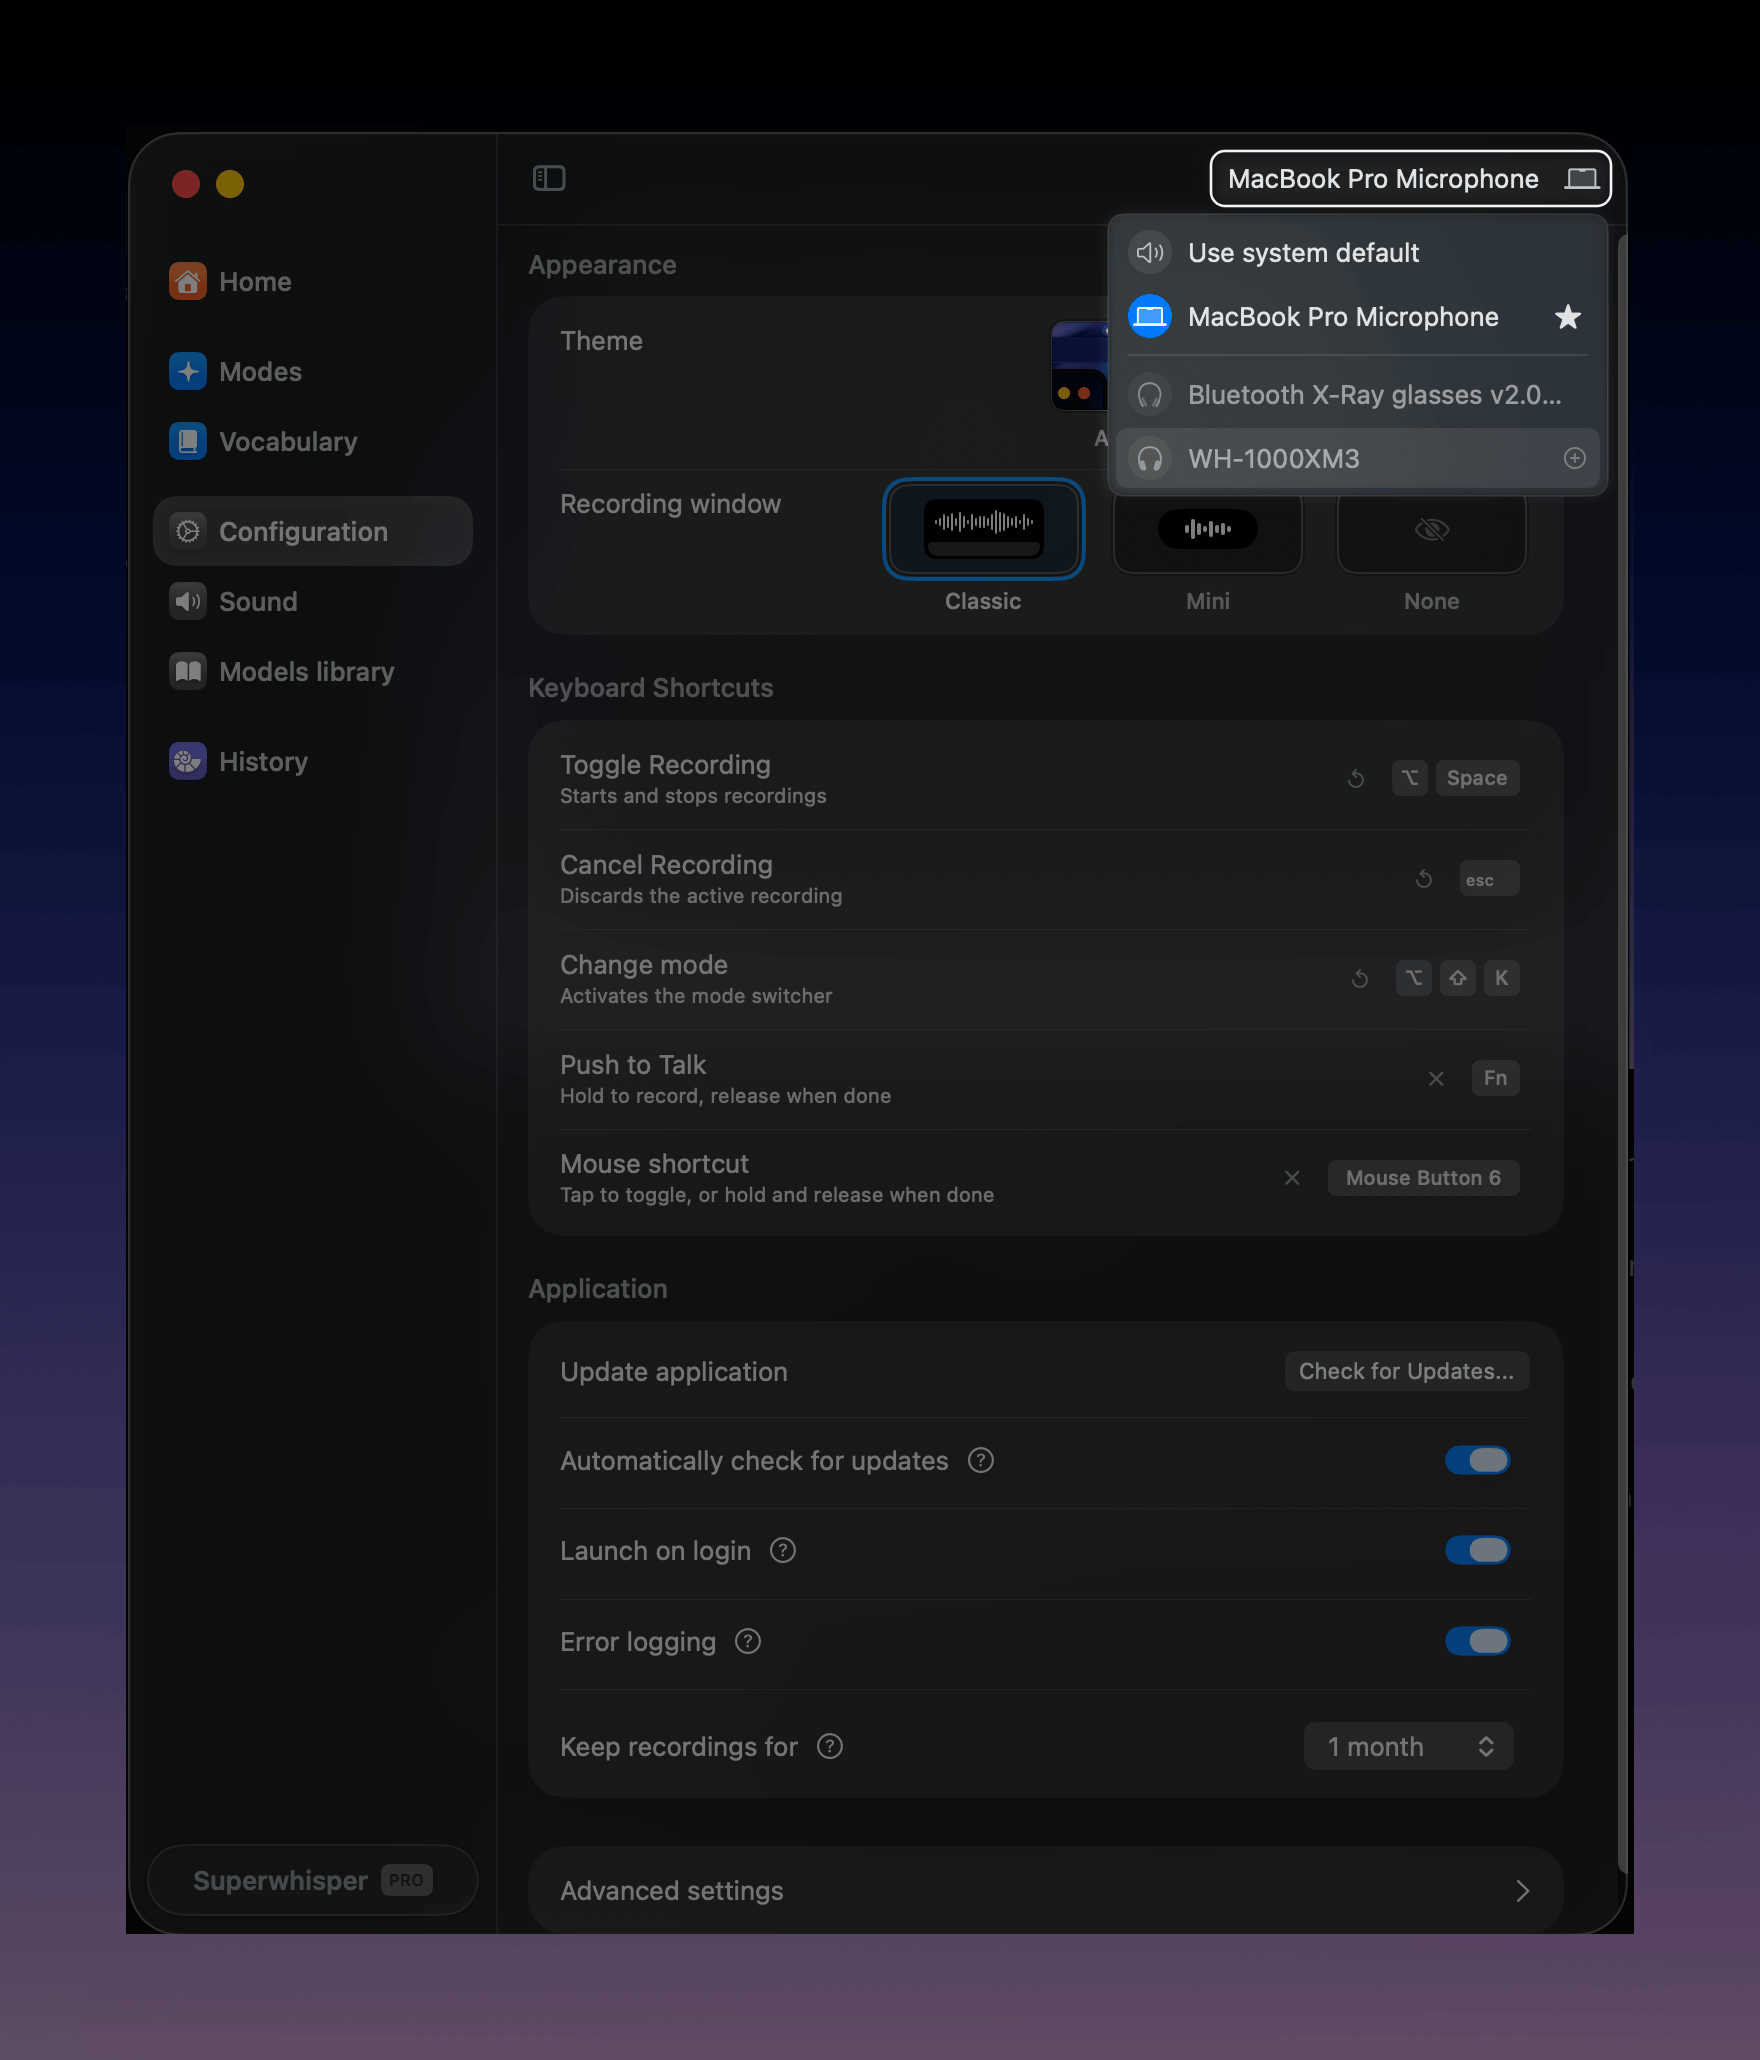
2
Confirm microphone permission
On macOS, open System Settings → Privacy & Security → Microphone and make sure Superwhisper is enabled. On Windows, check Settings → Privacy & security → Microphone.
3
Watch the waveform while you speak
Start a recording and talk. If the waveform doesn’t move, audio isn’t reaching the app. Try the built-in microphone to rule out a Bluetooth device problem.One exception: when a mode records system audio, the waveform stays still by design. Check History to confirm audio was captured.
4
Play back the recording
Open the dictation in History and play the audio. If the recording is silent, the input device was wrong or muted. If you can hear yourself clearly but still got the error, email support@superwhisper.com with the recording’s timestamp.
Enable Automatic volume adjustment in Settings → Sound. It sets your microphone level so quiet input doesn’t read as silence.
Stuck on processing
If dictations hang at the processing stage instead:- Check your connection: Cloud models need internet. Try a local model to confirm.
- Check the model finished downloading: A local model that’s still downloading can’t transcribe. Open Settings → Models library.
- Restart Superwhisper: retry the dictation from History. Your audio is already saved.
- Report it: turn on Error logging in Settings → Configuration, reproduce the problem once, and email support@superwhisper.com.