What we measure
1
Word error rate (WER)
The share of words that differ from a human transcript, counting every insertion, deletion, and substitution. Lower is better.
2
Response time
Seconds from the end of speech to a finished transcript, measured on dictation-length clips of 8 to 15 seconds. This is measured directly, not estimated from throughput, and reported as the median over the same runs the accuracy comes from.
3
Speed
How much faster than real time the model transcribes. At 20×, a minute of speech comes back in three seconds.
4
Recall and F-score
How many of the custom vocabulary terms actually spoken the model got right, and that figure balanced against words it wrongly changed to match one. This is what tells you whether custom vocabulary will hold up on your jargon.
How the blended score works
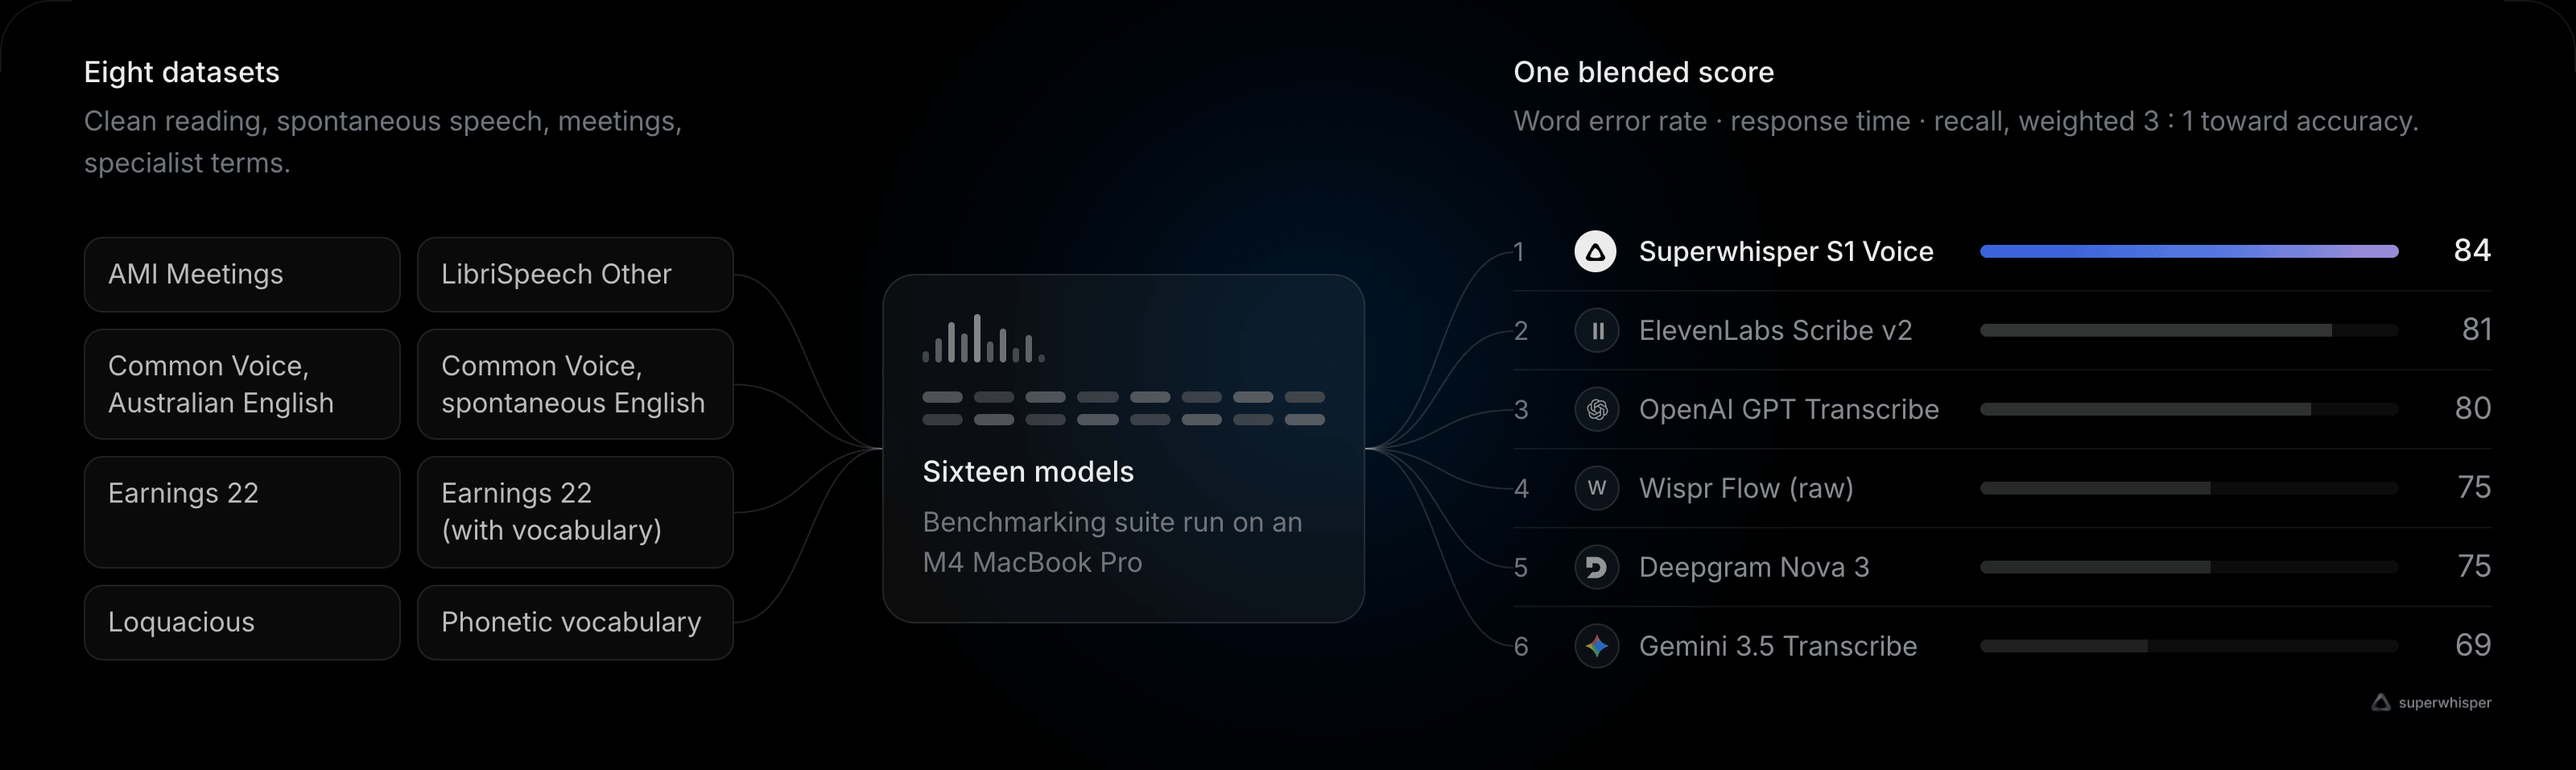
The leaderboard’s headline score puts accuracy and response time into one number out of 100, weighted three to one in favour of accuracy. A transcript you have to correct is not a fast transcript. Recall and F-score are reported alongside it but don’t feed into the score. Both ends of the scale are fixed values rather than a ranking against the field:- Accuracy scores zero at a 30% word error rate. At roughly one word in three wrong, a transcript is faster to retype than to fix.
- Response time scores full marks under one second, because you cannot beat instant, and zero at eight seconds.
Datasets
Eight sets, chosen to cover clean reading, spontaneous speech, meetings, and the specialist terms custom vocabulary is meant to catch. Each dataset counts once regardless of how many clips it holds, so a large easy corpus can’t paper over a small hard one.How the runs work
Local models are measured by driving the real Superwhisper app, not a reimplementation of it, so the result comes from the same engines and decode settings you get in the product. Cloud models are called over their public APIs. Competitor apps with no API are driven as apps. Every run writes its clip-level output to the benchmark repository along with the machine it ran on and the commit that produced it.Local models are run on M4 and M4 Max hardware, and each leaderboard row names the machine it ran on. Local model speed depends heavily on the hardware, so don’t assume these figures carry over to an older Mac. This is why the docs avoid claims like “fastest on any machine” for local models.
What the model tables show
The Speed and Accuracy columns on Voice models and Language models are relative ratings from 1 to 10, not benchmark output. They cover every model in the app, including the many that aren’t in the benchmark suite, so they can be compared in one table. When you need a measured figure, use the leaderboard. When you’re choosing between two models in the app, the ratings are the faster read.Where competitors win
The leaderboard publishes the rows where somebody else comes out ahead, because a benchmark that only shows your wins isn’t a benchmark. As of the September 2026 run, S1-Voice leads on blended score and word error rate, while ElevenLabs Scribe v2 and OpenAI GPT Transcribe lead on vocabulary recall and F-score.Full leaderboard
Every model, every dataset, with the runs behind each number.